
Deep Learning Models: A collection of various deep learning architectures, models, & their implementations (PyTorch or TensorFlow) in Jupyter Notebooks.
- Author: Chizoba Obasi
- Github Repo: https://github.com/chizkidd/deep-learning-models
!pip install watermark
Collecting watermark
  Downloading watermark-2.5.1-py3-none-any.whl.metadata (1.5 kB)
Requirement already satisfied: ipython>=6.0 in /usr/local/lib/python3.12/dist-packages (from watermark) (7.34.0)
Requirement already satisfied: importlib-metadata>=1.4 in /usr/local/lib/python3.12/dist-packages (from watermark) (8.7.0)
Requirement already satisfied: setuptools in /usr/local/lib/python3.12/dist-packages (from watermark) (75.2.0)
Requirement already satisfied: zipp>=3.20 in /usr/local/lib/python3.12/dist-packages (from importlib-metadata>=1.4->watermark) (3.23.0)
Collecting jedi>=0.16 (from ipython>=6.0->watermark)
  Downloading jedi-0.19.2-py2.py3-none-any.whl.metadata (22 kB)
Requirement already satisfied: decorator in /usr/local/lib/python3.12/dist-packages (from ipython>=6.0->watermark) (4.4.2)
Requirement already satisfied: pickleshare in /usr/local/lib/python3.12/dist-packages (from ipython>=6.0->watermark) (0.7.5)
Requirement already satisfied: traitlets>=4.2 in /usr/local/lib/python3.12/dist-packages (from ipython>=6.0->watermark) (5.7.1)
Requirement already satisfied: prompt-toolkit!=3.0.0,!=3.0.1,<3.1.0,>=2.0.0 in /usr/local/lib/python3.12/dist-packages (from ipython>=6.0->watermark) (3.0.52)
Requirement already satisfied: pygments in /usr/local/lib/python3.12/dist-packages (from ipython>=6.0->watermark) (2.19.2)
Requirement already satisfied: backcall in /usr/local/lib/python3.12/dist-packages (from ipython>=6.0->watermark) (0.2.0)
Requirement already satisfied: matplotlib-inline in /usr/local/lib/python3.12/dist-packages (from ipython>=6.0->watermark) (0.2.1)
Requirement already satisfied: pexpect>4.3 in /usr/local/lib/python3.12/dist-packages (from ipython>=6.0->watermark) (4.9.0)
Requirement already satisfied: parso<0.9.0,>=0.8.4 in /usr/local/lib/python3.12/dist-packages (from jedi>=0.16->ipython>=6.0->watermark) (0.8.5)
Requirement already satisfied: ptyprocess>=0.5 in /usr/local/lib/python3.12/dist-packages (from pexpect>4.3->ipython>=6.0->watermark) (0.7.0)
Requirement already satisfied: wcwidth in /usr/local/lib/python3.12/dist-packages (from prompt-toolkit!=3.0.0,!=3.0.1,<3.1.0,>=2.0.0->ipython>=6.0->watermark) (0.2.14)
Downloading watermark-2.5.1-py3-none-any.whl (7.8 kB)
Downloading jedi-0.19.2-py2.py3-none-any.whl (1.6 MB)
   ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 0.0/1.6 MB ? eta -:--:--
   ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 1.6/1.6 MB 86.2 MB/s eta 0:00:00
Installing collected packages: jedi, watermark
Successfully installed jedi-0.19.2 watermark-2.5.1
!pip install torchinfo
Collecting torchinfo
  Downloading torchinfo-1.8.0-py3-none-any.whl.metadata (21 kB)
Downloading torchinfo-1.8.0-py3-none-any.whl (23 kB)
Installing collected packages: torchinfo
Successfully installed torchinfo-1.8.0
%load_ext watermark
# %reload_ext watermark
%watermark -a 'Chizoba Obasi' -v -p torch
Author: Chizoba Obasi

Python implementation: CPython
Python version       : 3.12.12
IPython version      : 7.34.0

torch: 2.9.0+cu126
import torch
import torch.nn as nn
import torch.nn.functional as F
import torch.optim as optim
from torch.utils.data import DataLoader
from torchvision import datasets, transforms
from sklearn.model_selection import train_test_split

from torchinfo import summary

import matplotlib.image as mpimg
import matplotlib.pyplot as plt
%matplotlib inline

import pandas as pd
import numpy as np
import math
import time
import os
import random

if torch.cuda.is_available():
    torch.backends.cudnn.deterministic = True
def set_all_seeds(seed):
    os.environ["PL_GLOBAL_SEED"] = str(seed)
    random.seed(seed)
    np.random.seed(seed)
    torch.manual_seed(seed)
    torch.cuda.manual_seed_all(seed)
# Check if GPU is available and set the device
if torch.cuda.is_available():
    num_gpus = torch.cuda.device_count()
    print("Num GPUs Available: ", num_gpus)
    for i in range(num_gpus):
        gpu_name = torch.cuda.get_device_name(i)
        print(f"GPU {i}: {gpu_name}")
else:
    print("No GPU available.")
Num GPUs Available:  1
GPU 0: Tesla T4
ResNet: Residual Blocks
- Single Residual Block: The fundamental innovation of a Residual Block is the "shortcut connection" (or skip connection). Instead of forcing the layers to learn the underlying mapping H(x), we let them learn the residual mapping F(x) = H(x) - x. The output becomes F(x) + x. This allows the gradient to flow through the shortcut during backpropagation, effectively solving the vanishing gradient problem and allowing for much deeper architectures.

- Various Usages of Activation in residual Block: This diagram illustrates the placement of Batch Normalization (BN) and ReLU activation relative to the convolutional layers. While the original ResNet (2015) used Post-activation (applying ReLU after the addition), subsequent research (He et al., 2016) introduced Pre-activation ResNet. In the pre-activation version, BN and ReLU are applied before the weight layers, which eases optimization and improves the regularization of the model.

Types of Residual Block: ResNet architectures use two primary building blocks depending on the depth of the network:
- Basic Block: Used in ResNet-$18$ and ResNet-$34$. It consists of two consecutive $3 \times 3$ convolutional layers.
- Bottleneck Block: Used in deeper versions like ResNet-$50$, $101$, and $152$. It uses a triplet of $1 \times 1$, $3 \times 3$, and $1 \times 1$ convolutions. The $1 \times 1$ layers are used to first reduce (bottleneck) and then restore dimensions, significantly reducing the number of parameters and computational cost while maintaining performance.


ResNet-34 Classifier on CIFAR-10
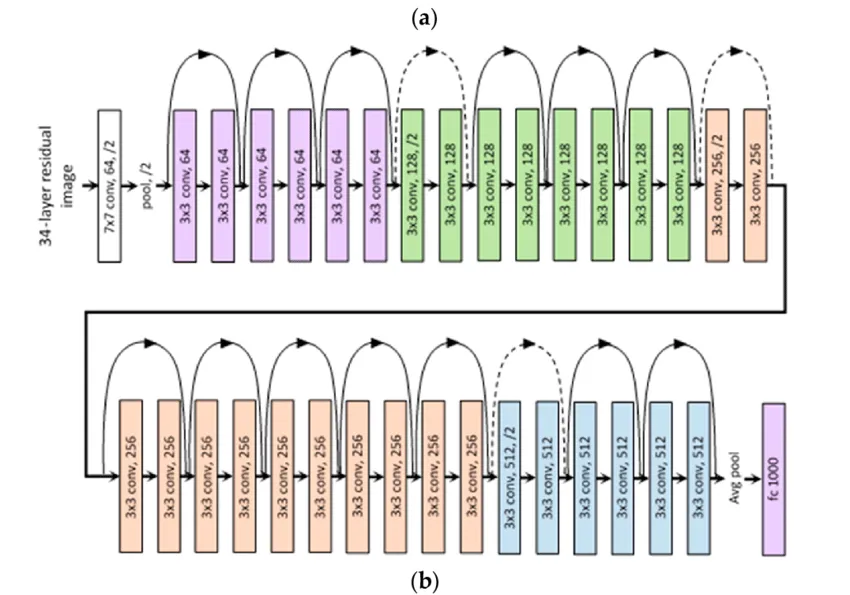
Network Architecture: The network in this notebook is an implementation of the ResNet-18 [1] architecture on the Cifar-10 dataset to train an image classifier.
| layer name | output size | 18-layer | 34-layer | 50-layer | 101-layer | 152-layer |
|---|---|---|---|---|---|---|
| conv1 | 112×112 | 7×7, 64, stride 2 | 7×7, 64, stride 2 | 7×7, 64, stride 2 | 7×7, 64, stride 2 | 7×7, 64, stride 2 |
| conv2_x | 56×56 | 3×3 max pool, stride 2 | 3×3 max pool, stride 2 | 3×3 max pool, stride 2 | 3×3 max pool, stride 2 | 3×3 max pool, stride 2 |
| $\begin{bmatrix} 3\times3, 64 \\ 3\times3, 64 \end{bmatrix} \times 2$ | $\begin{bmatrix} 3\times3, 64 \\ 3\times3, 64 \end{bmatrix} \times 3$ | $\begin{bmatrix} 1\times1, 64 \\ 3\times3, 64 \\ 1\times1, 256 \end{bmatrix} \times 3$ | $\begin{bmatrix} 1\times1, 64 \\ 3\times3, 64 \\ 1\times1, 256 \end{bmatrix} \times 3$ | $\begin{bmatrix} 1\times1, 64 \\ 3\times3, 64 \\ 1\times1, 256 \end{bmatrix} \times 3$ | ||
| conv3_x | 28×28 | $\begin{bmatrix} 3\times3, 128 \\ 3\times3, 128 \end{bmatrix} \times 2$ | $\begin{bmatrix} 3\times3, 128 \\ 3\times3, 128 \end{bmatrix} \times 4$ | $\begin{bmatrix} 1\times1, 128 \\ 3\times3, 128 \\ 1\times1, 512 \end{bmatrix} \times 4$ | $\begin{bmatrix} 1\times1, 128 \\ 3\times3, 128 \\ 1\times1, 512 \end{bmatrix} \times 4$ | $\begin{bmatrix} 1\times1, 128 \\ 3\times3, 128 \\ 1\times1, 512 \end{bmatrix} \times 8$ |
| conv4_x | 14×14 | $\begin{bmatrix} 3\times3, 256 \\ 3\times3, 256 \end{bmatrix} \times 2$ | $\begin{bmatrix} 3\times3, 256 \\ 3\times3, 256 \end{bmatrix} \times 6$ | $\begin{bmatrix} 1\times1, 256 \\ 3\times3, 256 \\ 1\times1, 1024 \end{bmatrix} \times 6$ | $\begin{bmatrix} 1\times1, 256 \\ 3\times3, 256 \\ 1\times1, 1024 \end{bmatrix} \times 23$ | $\begin{bmatrix} 1\times1, 256 \\ 3\times3, 256 \\ 1\times1, 1024 \end{bmatrix} \times 36$ |
| conv5_x | 7×7 | $\begin{bmatrix} 3\times3, 512 \\ 3\times3, 512 \end{bmatrix} \times 2$ | $\begin{bmatrix} 3\times3, 512 \\ 3\times3, 512 \end{bmatrix} \times 3$ | $\begin{bmatrix} 1\times1, 512 \\ 3\times3, 512 \\ 1\times1, 2048 \end{bmatrix} \times 3$ | $\begin{bmatrix} 1\times1, 512 \\ 3\times3, 512 \\ 1\times1, 2048 \end{bmatrix} \times 3$ | $\begin{bmatrix} 1\times1, 512 \\ 3\times3, 512 \\ 1\times1, 2048 \end{bmatrix} \times 3$ |
| 1×1 | avg pool, 1000-d fc, softmax | avg pool, 1000-d fc, softmax | avg pool, 1000-d fc, softmax | avg pool, 1000-d fc, softmax | avg pool, 1000-d fc, softmax | |
| FLOPs | 1.8 × 10⁹ | 3.6 × 10⁹ | 3.8 × 10⁹ | 7.6 × 10⁹ | 11.3 × 10⁹ |
Table adapted from ResNet paper
Key Notes on the Architecture:
- Building Blocks: The 18-layer and 34-layer networks use basic blocks (two 3×3 convs), while the deeper 50/101/152-layer networks use bottleneck blocks (1×1, 3×3, and 1×1 convs).
- Downsampling: Downsampling is performed by
conv3_1,conv4_1, andconv5_1with a stride of 2. - Global Average Pooling: This is used at the end of the convolutional layers to reduce the spatial dimensions to 1×1 before the fully connected layer.
The following figure illustrates residual blocks with skip connections such that the input passed via the shortcut matches the dimensions of the main path's output, which allows the network to learn identity functions.

The ResNet-18 architecture actually uses residual blocks with skip connections such that the input passed via the shortcut matches is resized to dimensions of the main path's output. Such a residual block is illustrated below:

Improvements over LeNet, AlexNet, VGG:
- Skip Connections: Unlike VGG and AlexNet, ResNet uses "identity mapping" which solves the vanishing gradient problem.
- Global Average Pooling: Instead of a huge Flatten + Dense layer (like in AlexNet), we use
avg_pool2d. This significantly reduces parameter count and prevents overfitting. - Batch Normalization: ResNet relies heavily on BN after every convolution to stabilize training at a higher learning rate.
REFERENCES:
He, K., Zhang, X., Ren, S., & Sun, J. "Deep residual learning for image recognition." Proceedings of the IEEE conference on computer vision and pattern recognition. 2016. (770-77).
Johnson, J. (2022, February 2). Lecture 8: CNN Architectures [PowerPoint Slides]. University of Michigan EECS 498/598: Deep Learning for Computer Vision. pp 77-109. https://web.eecs.umich.edu/~justincj/slides/eecs498/WI2022/598_WI2022_lecture08.pdf
Mahdid, Y. (2024.). deep-learning-model-explained: ResNet [Source code]. GitHub. https://github.com/yacineMahdid/deep-learning-model-explained/tree/main/resnet
##########################
### SETTINGS
##########################

# Hyperparameters
RANDOM_SEED = 123
BATCH_SIZE = 128 #256
LEARNING_RATE = 0.001
NUM_EPOCHS = 20
INPUT_SIZE = 32 # CIFAR-10 is 32x32
NUM_CLASSES = 10

# Set device
device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
print(device)
cuda
# Mean and Std Dev for CIFAR-10 (3 channels)
CIFAR_MEAN = (0.4914, 0.4822, 0.4465)
CIFAR_STD = (0.2471, 0.2435, 0.2616)

train_transforms = transforms.Compose([
    transforms.RandomRotation(15),
    transforms.RandomCrop(32, padding=4, padding_mode='reflect'),
    transforms.RandomHorizontalFlip(),
    transforms.ToTensor(),
    transforms.Normalize(CIFAR_MEAN, CIFAR_STD)
])

test_transforms = transforms.Compose([
    transforms.ToTensor(),
    transforms.Normalize(CIFAR_MEAN, CIFAR_STD)
])

# Load Datasets
train_dataset = datasets.CIFAR10(root='./data', train=True, download=True, transform=train_transforms)
test_dataset = datasets.CIFAR10(root='./data', train=False, download=True, transform=test_transforms)

# Split training set into training and validation sets
train_size = int(0.9 * len(train_dataset))
val_size = len(train_dataset) - train_size
train_subset, val_subset = torch.utils.data.random_split(train_dataset, [train_size, val_size])

# Create DataLoaders
train_loader = DataLoader(train_subset, batch_size=BATCH_SIZE, shuffle=True)
val_loader = DataLoader(val_subset, batch_size=BATCH_SIZE, shuffle=False)
test_loader = DataLoader(test_dataset, batch_size=BATCH_SIZE, shuffle=False)
100%|██████████| 170M/170M [00:14<00:00, 12.1MB/s]
2. Model Creation
Notes:
- This implementation uses a $3 \times 3$ initial convolution (instead of $7 \times 7$) and removes the initial MaxPool to preserve the spatial resolution of the small $32 \times 32$ images.
class BasicBlock(nn.Module):
    expansion = 1
    def __init__(self, in_planes, planes, stride=1):
        super(BasicBlock, self).__init__()
        self.conv1 = nn.Conv2d(in_planes, planes, kernel_size=3, stride=stride, padding=1, bias=False)
        self.bn1 = nn.BatchNorm2d(planes)
        self.conv2 = nn.Conv2d(planes, planes, kernel_size=3, stride=1, padding=1, bias=False)
        self.bn2 = nn.BatchNorm2d(planes)
        self.relu = nn.ReLU(inplace=True)

        self.shortcut = nn.Sequential()
        if stride != 1 or in_planes != self.expansion*planes:
            self.shortcut = nn.Sequential(
                nn.Conv2d(in_planes, self.expansion*planes, kernel_size=1, stride=stride, bias=False),
                nn.BatchNorm2d(self.expansion*planes)
            )

    def forward(self, x):
        residual = self.shortcut(x)
        out = self.relu(self.bn1(self.conv1(x)))  # conv->batchnorm->relu
        out = self.bn2(self.conv2(out))           # conv->batchnorm
        out += residual                           # skip connection
        out = torch.relu(out)                     # relu
        return out

class ResNet(nn.Module):
    def __init__(self, block, num_blocks, num_classes=10):
        super(ResNet, self).__init__()
        self.in_planes = 64
        self.conv1 = nn.Conv2d(3, 64, kernel_size=3, stride=1, padding=1, bias=False)
        self.bn1 = nn.BatchNorm2d(64)
        self.relu = nn.ReLU(inplace=True)

        self.layer1 = self._make_layer(block, 64, num_blocks[0], stride=1)
        self.layer2 = self._make_layer(block, 128, num_blocks[1], stride=2)
        self.layer3 = self._make_layer(block, 256, num_blocks[2], stride=2)
        self.layer4 = self._make_layer(block, 512, num_blocks[3], stride=2)

        self.avgpool = nn.AdaptiveAvgPool2d((1, 1))
        self.linear = nn.Linear(512*block.expansion, num_classes)

    def _make_layer(self, block, planes, num_blocks, stride):
        strides = [stride] + [1]*(num_blocks-1)
        layers = []
        for s in strides:
            layers.append(block(self.in_planes, planes, s))
            self.in_planes = planes * block.expansion
        return nn.Sequential(*layers)

    def forward(self, x):
        out = torch.relu(self.bn1(self.conv1(x)))
        out = self.layer1(out)
        out = self.layer2(out)
        out = self.layer3(out)
        out = self.layer4(out)

        out = self.avgpool(out)
        out = torch.flatten(out, 1)
        out = self.linear(out)
        return out

def ResNet34():
    return ResNet(BasicBlock, [3, 4, 6, 3])
def test_model_dims():
    # Create a dummy batch: 2 images, 3 channels, 32x32 size
    x = torch.randn(2, 3, 32, 32).to(device)

    # Initialize model
    net = ResNet34().to(device)

    # Forward pass
    y = net(x)

    print(f"Input Shape: {x.shape}")
    print(f"Output Shape: {y.shape}") # Should be [2, 10]

    if y.shape == (2, 10):
        print("✅ Sanity Check Passed: Dimensions are correct for CIFAR-10!")
    else:
        print("❌ Sanity Check Failed: Check your stride or pooling layers.")

test_model_dims()
Input Shape: torch.Size([2, 3, 32, 32])
Output Shape: torch.Size([2, 10])
✅ Sanity Check Passed: Dimensions are correct for CIFAR-10!
set_all_seeds(RANDOM_SEED)
model = ResNet34().to(device)
# Model parameter details
summary(model,
        input_size=(BATCH_SIZE, 3, INPUT_SIZE, INPUT_SIZE),
        # verbose=1,
        col_names=["input_size", "output_size", "num_params", "kernel_size", "mult_adds"]
       )
===================================================================================================================================================================== Layer (type:depth-idx) Input Shape Output Shape Param # Kernel Shape Mult-Adds ===================================================================================================================================================================== ResNet [128, 3, 32, 32] [128, 10] -- -- -- ├─Conv2d: 1-1 [128, 3, 32, 32] [128, 64, 32, 32] 1,728 [3, 3] 226,492,416 ├─BatchNorm2d: 1-2 [128, 64, 32, 32] [128, 64, 32, 32] 128 -- 16,384 ├─Sequential: 1-3 [128, 64, 32, 32] [128, 64, 32, 32] -- -- -- │ └─BasicBlock: 2-1 [128, 64, 32, 32] [128, 64, 32, 32] -- -- -- │ │ └─Sequential: 3-1 [128, 64, 32, 32] [128, 64, 32, 32] -- -- -- │ │ └─Conv2d: 3-2 [128, 64, 32, 32] [128, 64, 32, 32] 36,864 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-3 [128, 64, 32, 32] [128, 64, 32, 32] 128 -- 16,384 │ │ └─ReLU: 3-4 [128, 64, 32, 32] [128, 64, 32, 32] -- -- -- │ │ └─Conv2d: 3-5 [128, 64, 32, 32] [128, 64, 32, 32] 36,864 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-6 [128, 64, 32, 32] [128, 64, 32, 32] 128 -- 16,384 │ └─BasicBlock: 2-2 [128, 64, 32, 32] [128, 64, 32, 32] -- -- -- │ │ └─Sequential: 3-7 [128, 64, 32, 32] [128, 64, 32, 32] -- -- -- │ │ └─Conv2d: 3-8 [128, 64, 32, 32] [128, 64, 32, 32] 36,864 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-9 [128, 64, 32, 32] [128, 64, 32, 32] 128 -- 16,384 │ │ └─ReLU: 3-10 [128, 64, 32, 32] [128, 64, 32, 32] -- -- -- │ │ └─Conv2d: 3-11 [128, 64, 32, 32] [128, 64, 32, 32] 36,864 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-12 [128, 64, 32, 32] [128, 64, 32, 32] 128 -- 16,384 │ └─BasicBlock: 2-3 [128, 64, 32, 32] [128, 64, 32, 32] -- -- -- │ │ └─Sequential: 3-13 [128, 64, 32, 32] [128, 64, 32, 32] -- -- -- │ │ └─Conv2d: 3-14 [128, 64, 32, 32] [128, 64, 32, 32] 36,864 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-15 [128, 64, 32, 32] [128, 64, 32, 32] 128 -- 16,384 │ │ └─ReLU: 3-16 [128, 64, 32, 32] [128, 64, 32, 32] -- -- -- │ │ └─Conv2d: 3-17 [128, 64, 32, 32] [128, 64, 32, 32] 36,864 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-18 [128, 64, 32, 32] [128, 64, 32, 32] 128 -- 16,384 ├─Sequential: 1-4 [128, 64, 32, 32] [128, 128, 16, 16] -- -- -- │ └─BasicBlock: 2-4 [128, 64, 32, 32] [128, 128, 16, 16] -- -- -- │ │ └─Sequential: 3-19 [128, 64, 32, 32] [128, 128, 16, 16] 8,448 -- 268,468,224 │ │ └─Conv2d: 3-20 [128, 64, 32, 32] [128, 128, 16, 16] 73,728 [3, 3] 2,415,919,104 │ │ └─BatchNorm2d: 3-21 [128, 128, 16, 16] [128, 128, 16, 16] 256 -- 32,768 │ │ └─ReLU: 3-22 [128, 128, 16, 16] [128, 128, 16, 16] -- -- -- │ │ └─Conv2d: 3-23 [128, 128, 16, 16] [128, 128, 16, 16] 147,456 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-24 [128, 128, 16, 16] [128, 128, 16, 16] 256 -- 32,768 │ └─BasicBlock: 2-5 [128, 128, 16, 16] [128, 128, 16, 16] -- -- -- │ │ └─Sequential: 3-25 [128, 128, 16, 16] [128, 128, 16, 16] -- -- -- │ │ └─Conv2d: 3-26 [128, 128, 16, 16] [128, 128, 16, 16] 147,456 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-27 [128, 128, 16, 16] [128, 128, 16, 16] 256 -- 32,768 │ │ └─ReLU: 3-28 [128, 128, 16, 16] [128, 128, 16, 16] -- -- -- │ │ └─Conv2d: 3-29 [128, 128, 16, 16] [128, 128, 16, 16] 147,456 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-30 [128, 128, 16, 16] [128, 128, 16, 16] 256 -- 32,768 │ └─BasicBlock: 2-6 [128, 128, 16, 16] [128, 128, 16, 16] -- -- -- │ │ └─Sequential: 3-31 [128, 128, 16, 16] [128, 128, 16, 16] -- -- -- │ │ └─Conv2d: 3-32 [128, 128, 16, 16] [128, 128, 16, 16] 147,456 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-33 [128, 128, 16, 16] [128, 128, 16, 16] 256 -- 32,768 │ │ └─ReLU: 3-34 [128, 128, 16, 16] [128, 128, 16, 16] -- -- -- │ │ └─Conv2d: 3-35 [128, 128, 16, 16] [128, 128, 16, 16] 147,456 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-36 [128, 128, 16, 16] [128, 128, 16, 16] 256 -- 32,768 │ └─BasicBlock: 2-7 [128, 128, 16, 16] [128, 128, 16, 16] -- -- -- │ │ └─Sequential: 3-37 [128, 128, 16, 16] [128, 128, 16, 16] -- -- -- │ │ └─Conv2d: 3-38 [128, 128, 16, 16] [128, 128, 16, 16] 147,456 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-39 [128, 128, 16, 16] [128, 128, 16, 16] 256 -- 32,768 │ │ └─ReLU: 3-40 [128, 128, 16, 16] [128, 128, 16, 16] -- -- -- │ │ └─Conv2d: 3-41 [128, 128, 16, 16] [128, 128, 16, 16] 147,456 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-42 [128, 128, 16, 16] [128, 128, 16, 16] 256 -- 32,768 ├─Sequential: 1-5 [128, 128, 16, 16] [128, 256, 8, 8] -- -- -- │ └─BasicBlock: 2-8 [128, 128, 16, 16] [128, 256, 8, 8] -- -- -- │ │ └─Sequential: 3-43 [128, 128, 16, 16] [128, 256, 8, 8] 33,280 -- 268,500,992 │ │ └─Conv2d: 3-44 [128, 128, 16, 16] [128, 256, 8, 8] 294,912 [3, 3] 2,415,919,104 │ │ └─BatchNorm2d: 3-45 [128, 256, 8, 8] [128, 256, 8, 8] 512 -- 65,536 │ │ └─ReLU: 3-46 [128, 256, 8, 8] [128, 256, 8, 8] -- -- -- │ │ └─Conv2d: 3-47 [128, 256, 8, 8] [128, 256, 8, 8] 589,824 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-48 [128, 256, 8, 8] [128, 256, 8, 8] 512 -- 65,536 │ └─BasicBlock: 2-9 [128, 256, 8, 8] [128, 256, 8, 8] -- -- -- │ │ └─Sequential: 3-49 [128, 256, 8, 8] [128, 256, 8, 8] -- -- -- │ │ └─Conv2d: 3-50 [128, 256, 8, 8] [128, 256, 8, 8] 589,824 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-51 [128, 256, 8, 8] [128, 256, 8, 8] 512 -- 65,536 │ │ └─ReLU: 3-52 [128, 256, 8, 8] [128, 256, 8, 8] -- -- -- │ │ └─Conv2d: 3-53 [128, 256, 8, 8] [128, 256, 8, 8] 589,824 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-54 [128, 256, 8, 8] [128, 256, 8, 8] 512 -- 65,536 │ └─BasicBlock: 2-10 [128, 256, 8, 8] [128, 256, 8, 8] -- -- -- │ │ └─Sequential: 3-55 [128, 256, 8, 8] [128, 256, 8, 8] -- -- -- │ │ └─Conv2d: 3-56 [128, 256, 8, 8] [128, 256, 8, 8] 589,824 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-57 [128, 256, 8, 8] [128, 256, 8, 8] 512 -- 65,536 │ │ └─ReLU: 3-58 [128, 256, 8, 8] [128, 256, 8, 8] -- -- -- │ │ └─Conv2d: 3-59 [128, 256, 8, 8] [128, 256, 8, 8] 589,824 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-60 [128, 256, 8, 8] [128, 256, 8, 8] 512 -- 65,536 │ └─BasicBlock: 2-11 [128, 256, 8, 8] [128, 256, 8, 8] -- -- -- │ │ └─Sequential: 3-61 [128, 256, 8, 8] [128, 256, 8, 8] -- -- -- │ │ └─Conv2d: 3-62 [128, 256, 8, 8] [128, 256, 8, 8] 589,824 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-63 [128, 256, 8, 8] [128, 256, 8, 8] 512 -- 65,536 │ │ └─ReLU: 3-64 [128, 256, 8, 8] [128, 256, 8, 8] -- -- -- │ │ └─Conv2d: 3-65 [128, 256, 8, 8] [128, 256, 8, 8] 589,824 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-66 [128, 256, 8, 8] [128, 256, 8, 8] 512 -- 65,536 │ └─BasicBlock: 2-12 [128, 256, 8, 8] [128, 256, 8, 8] -- -- -- │ │ └─Sequential: 3-67 [128, 256, 8, 8] [128, 256, 8, 8] -- -- -- │ │ └─Conv2d: 3-68 [128, 256, 8, 8] [128, 256, 8, 8] 589,824 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-69 [128, 256, 8, 8] [128, 256, 8, 8] 512 -- 65,536 │ │ └─ReLU: 3-70 [128, 256, 8, 8] [128, 256, 8, 8] -- -- -- │ │ └─Conv2d: 3-71 [128, 256, 8, 8] [128, 256, 8, 8] 589,824 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-72 [128, 256, 8, 8] [128, 256, 8, 8] 512 -- 65,536 │ └─BasicBlock: 2-13 [128, 256, 8, 8] [128, 256, 8, 8] -- -- -- │ │ └─Sequential: 3-73 [128, 256, 8, 8] [128, 256, 8, 8] -- -- -- │ │ └─Conv2d: 3-74 [128, 256, 8, 8] [128, 256, 8, 8] 589,824 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-75 [128, 256, 8, 8] [128, 256, 8, 8] 512 -- 65,536 │ │ └─ReLU: 3-76 [128, 256, 8, 8] [128, 256, 8, 8] -- -- -- │ │ └─Conv2d: 3-77 [128, 256, 8, 8] [128, 256, 8, 8] 589,824 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-78 [128, 256, 8, 8] [128, 256, 8, 8] 512 -- 65,536 ├─Sequential: 1-6 [128, 256, 8, 8] [128, 512, 4, 4] -- -- -- │ └─BasicBlock: 2-14 [128, 256, 8, 8] [128, 512, 4, 4] -- -- -- │ │ └─Sequential: 3-79 [128, 256, 8, 8] [128, 512, 4, 4] 132,096 -- 268,566,528 │ │ └─Conv2d: 3-80 [128, 256, 8, 8] [128, 512, 4, 4] 1,179,648 [3, 3] 2,415,919,104 │ │ └─BatchNorm2d: 3-81 [128, 512, 4, 4] [128, 512, 4, 4] 1,024 -- 131,072 │ │ └─ReLU: 3-82 [128, 512, 4, 4] [128, 512, 4, 4] -- -- -- │ │ └─Conv2d: 3-83 [128, 512, 4, 4] [128, 512, 4, 4] 2,359,296 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-84 [128, 512, 4, 4] [128, 512, 4, 4] 1,024 -- 131,072 │ └─BasicBlock: 2-15 [128, 512, 4, 4] [128, 512, 4, 4] -- -- -- │ │ └─Sequential: 3-85 [128, 512, 4, 4] [128, 512, 4, 4] -- -- -- │ │ └─Conv2d: 3-86 [128, 512, 4, 4] [128, 512, 4, 4] 2,359,296 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-87 [128, 512, 4, 4] [128, 512, 4, 4] 1,024 -- 131,072 │ │ └─ReLU: 3-88 [128, 512, 4, 4] [128, 512, 4, 4] -- -- -- │ │ └─Conv2d: 3-89 [128, 512, 4, 4] [128, 512, 4, 4] 2,359,296 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-90 [128, 512, 4, 4] [128, 512, 4, 4] 1,024 -- 131,072 │ └─BasicBlock: 2-16 [128, 512, 4, 4] [128, 512, 4, 4] -- -- -- │ │ └─Sequential: 3-91 [128, 512, 4, 4] [128, 512, 4, 4] -- -- -- │ │ └─Conv2d: 3-92 [128, 512, 4, 4] [128, 512, 4, 4] 2,359,296 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-93 [128, 512, 4, 4] [128, 512, 4, 4] 1,024 -- 131,072 │ │ └─ReLU: 3-94 [128, 512, 4, 4] [128, 512, 4, 4] -- -- -- │ │ └─Conv2d: 3-95 [128, 512, 4, 4] [128, 512, 4, 4] 2,359,296 [3, 3] 4,831,838,208 │ │ └─BatchNorm2d: 3-96 [128, 512, 4, 4] [128, 512, 4, 4] 1,024 -- 131,072 ├─AdaptiveAvgPool2d: 1-7 [128, 512, 4, 4] [128, 512, 1, 1] -- -- -- ├─Linear: 1-8 [128, 512] [128, 10] 5,130 -- 656,640 ===================================================================================================================================================================== Total params: 21,282,122 Trainable params: 21,282,122 Non-trainable params: 0 Total mult-adds (Units.GIGABYTES): 148.41 ===================================================================================================================================================================== Input size (MB): 1.57 Forward/backward pass size (MB): 2097.16 Params size (MB): 85.13 Estimated Total Size (MB): 2183.86 =====================================================================================================================================================================
criterion = nn.CrossEntropyLoss()
optimizer = optim.Adam(model.parameters(), lr=LEARNING_RATE)
# optimizer = optim.SGD(model.parameters(), lr=0.1, momentum=0.9, weight_decay=5e-4)
scheduler = optim.lr_scheduler.CosineAnnealingLR(optimizer, T_max=200)
# Function to calculate accuracy
def calculate_accuracy(loader):
    model.eval()
    correct = 0
    total = 0
    with torch.no_grad():
        for inputs, labels in loader:
            inputs, labels = inputs.to(device), labels.to(device)
            outputs = model(inputs)
            _, predicted = torch.max(outputs.data, 1)
            total += labels.size(0)
            correct += (predicted == labels).sum().item()
    return 100 * correct / total

# Training Loop
start_time = time.time()
history = {'train_loss': [], 'val_loss': [], 'train_acc': [], 'val_acc': [], 'lrs': []}

print(f"Starting training on {device}...")

for epoch in range(NUM_EPOCHS):
    model.train()
    running_loss = 0.0
    for i, (inputs, labels) in enumerate(train_loader):
        inputs, labels = inputs.to(device), labels.to(device)

        optimizer.zero_grad()
        outputs = model(inputs)
        loss = criterion(outputs, labels)
        loss.backward()
        optimizer.step()

        running_loss += loss.item() * inputs.size(0)

    train_loss = running_loss / len(train_subset)
    train_acc = calculate_accuracy(train_loader)

    # Calculate validation loss and accuracy
    model.eval()
    val_loss = 0.0
    with torch.no_grad():
        for inputs, labels in val_loader:
            inputs, labels = inputs.to(device), labels.to(device)
            outputs = model(inputs)
            loss = criterion(outputs, labels)
            val_loss += loss.item() * inputs.size(0)

    val_loss /= len(val_subset)
    val_acc = calculate_accuracy(val_loader)

    scheduler.step()
    current_lr = optimizer.param_groups[0]['lr']

    history['train_loss'].append(train_loss)
    history['val_loss'].append(val_loss)
    history['train_acc'].append(train_acc)
    history['val_acc'].append(val_acc)
    history['lrs'].append(current_lr)

    print(f'Epoch {epoch + 1}/{NUM_EPOCHS} | '
          f'Train Loss: {train_loss:.5f}, '
          f'Train Accuracy: {train_acc:.2f}% | '
          f'Val Loss: {val_loss:.5f}, '
          f'Val Accuracy: {val_acc:.2f}% | '
          f'Learning Rate: {current_lr:.8f}')

print('\nTotal Training Time: %.2f min' % ((time.time() - start_time)/60))

# Final Evaluation
test_accuracy = calculate_accuracy(test_loader)
print(f'\nTest Accuracy: {test_accuracy:.2f}%')
Starting training on cuda...
Epoch 1/20 | Train Loss: 1.67233, Train Accuracy: 48.32% | Val Loss: 1.47149, Val Accuracy: 48.50% | Learning Rate: 0.00099994
Epoch 2/20 | Train Loss: 1.26060, Train Accuracy: 56.49% | Val Loss: 1.27459, Val Accuracy: 56.64% | Learning Rate: 0.00099975
Epoch 3/20 | Train Loss: 1.06959, Train Accuracy: 59.50% | Val Loss: 1.14243, Val Accuracy: 59.58% | Learning Rate: 0.00099944
Epoch 4/20 | Train Loss: 0.92817, Train Accuracy: 68.76% | Val Loss: 0.90130, Val Accuracy: 67.68% | Learning Rate: 0.00099901
Epoch 5/20 | Train Loss: 0.80569, Train Accuracy: 71.44% | Val Loss: 0.81939, Val Accuracy: 70.92% | Learning Rate: 0.00099846
Epoch 6/20 | Train Loss: 0.70872, Train Accuracy: 74.54% | Val Loss: 0.76517, Val Accuracy: 74.52% | Learning Rate: 0.00099778
Epoch 7/20 | Train Loss: 0.63793, Train Accuracy: 78.95% | Val Loss: 0.62078, Val Accuracy: 78.22% | Learning Rate: 0.00099698
Epoch 8/20 | Train Loss: 0.58331, Train Accuracy: 78.85% | Val Loss: 0.63805, Val Accuracy: 77.88% | Learning Rate: 0.00099606
Epoch 9/20 | Train Loss: 0.53209, Train Accuracy: 81.64% | Val Loss: 0.57742, Val Accuracy: 80.36% | Learning Rate: 0.00099501
Epoch 10/20 | Train Loss: 0.50330, Train Accuracy: 82.19% | Val Loss: 0.57732, Val Accuracy: 81.14% | Learning Rate: 0.00099384
Epoch 11/20 | Train Loss: 0.46496, Train Accuracy: 85.64% | Val Loss: 0.47474, Val Accuracy: 83.74% | Learning Rate: 0.00099255
Epoch 12/20 | Train Loss: 0.43417, Train Accuracy: 84.42% | Val Loss: 0.51419, Val Accuracy: 83.02% | Learning Rate: 0.00099114
Epoch 13/20 | Train Loss: 0.41214, Train Accuracy: 85.11% | Val Loss: 0.49720, Val Accuracy: 83.32% | Learning Rate: 0.00098961
Epoch 14/20 | Train Loss: 0.38744, Train Accuracy: 86.61% | Val Loss: 0.46345, Val Accuracy: 84.58% | Learning Rate: 0.00098796
Epoch 15/20 | Train Loss: 0.36260, Train Accuracy: 88.44% | Val Loss: 0.40947, Val Accuracy: 86.38% | Learning Rate: 0.00098618
Epoch 16/20 | Train Loss: 0.34725, Train Accuracy: 83.81% | Val Loss: 0.54141, Val Accuracy: 80.86% | Learning Rate: 0.00098429
Epoch 17/20 | Train Loss: 0.32823, Train Accuracy: 88.47% | Val Loss: 0.42200, Val Accuracy: 85.78% | Learning Rate: 0.00098228
Epoch 18/20 | Train Loss: 0.30927, Train Accuracy: 90.31% | Val Loss: 0.37083, Val Accuracy: 87.40% | Learning Rate: 0.00098015
Epoch 19/20 | Train Loss: 0.29038, Train Accuracy: 87.41% | Val Loss: 0.47149, Val Accuracy: 84.46% | Learning Rate: 0.00097790
Epoch 20/20 | Train Loss: 0.27757, Train Accuracy: 90.18% | Val Loss: 0.38308, Val Accuracy: 86.08% | Learning Rate: 0.00097553

Total Training Time: 48.93 min

Test Accuracy: 88.88%
def plot_history(history):
    """
    Plots the training and validation loss, accuracy, and learning rate
    from a PyTorch history dictionary.

    Args:
        history (dict): Dictionary containing training metrics.
                        Expected keys: 'train_loss', 'val_loss', 'train_acc', 'val_acc', 'lrs'.
    """
    epochs = range(len(history['train_loss']))

    plt.figure(figsize=(18, 5))

    # Plot 1: Loss
    plt.subplot(1, 3, 1)
    plt.plot(epochs, history['train_loss'], label='Training Loss')
    plt.plot(epochs, history['val_loss'], label='Validation Loss')
    plt.title('Loss')
    plt.xlabel('Epochs')
    plt.ylabel('Loss')
    plt.legend()
    # plt.grid(True)

    # Plot 2: Accuracy
    plt.subplot(1, 3, 2)
    plt.plot(epochs, history['train_acc'], label='Training Accuracy')
    plt.plot(epochs, history['val_acc'], label='Validation Accuracy')
    plt.title('Accuracy')
    plt.xlabel('Epochs')
    plt.ylabel('Accuracy')
    plt.legend()
    # plt.grid(True)

    # Plot 3: Learning Rate
    plt.subplot(1, 3, 3)
    plt.plot(epochs, history['lrs'], label='Learning Rate', color='orange')
    plt.title('Learning Rate')
    plt.xlabel('Epochs')
    plt.ylabel('Learning Rate')
    plt.legend()
    # plt.grid(True)

    plt.tight_layout()
    plt.show()
    # plt.savefig()
plot_history(history)

%watermark -iv
matplotlib : 3.10.0
numpy      : 2.0.2
pandas     : 2.2.2
sklearn    : 1.6.1
torch      : 2.9.0+cu126
torchinfo  : 1.8.0
torchvision: 0.24.0+cu126
