
Deep Learning Models: A collection of various deep learning architectures, models, & their implementations (PyTorch or TensorFlow) in Jupyter Notebooks.
- Author: Chizoba Obasi
- Github Repo: https://github.com/chizkidd/deep-learning-models
In [1]:
!pip install watermark
Collecting watermark
  Downloading watermark-2.6.0-py3-none-any.whl.metadata (15 kB)
Requirement already satisfied: ipython>=6.0 in /usr/local/lib/python3.12/dist-packages (from watermark) (7.34.0)
Requirement already satisfied: importlib-metadata>=1.4 in /usr/local/lib/python3.12/dist-packages (from watermark) (8.7.0)
Requirement already satisfied: setuptools in /usr/local/lib/python3.12/dist-packages (from watermark) (75.2.0)
Requirement already satisfied: zipp>=3.20 in /usr/local/lib/python3.12/dist-packages (from importlib-metadata>=1.4->watermark) (3.23.0)
Collecting jedi>=0.16 (from ipython>=6.0->watermark)
  Downloading jedi-0.19.2-py2.py3-none-any.whl.metadata (22 kB)
Requirement already satisfied: decorator in /usr/local/lib/python3.12/dist-packages (from ipython>=6.0->watermark) (4.4.2)
Requirement already satisfied: pickleshare in /usr/local/lib/python3.12/dist-packages (from ipython>=6.0->watermark) (0.7.5)
Requirement already satisfied: traitlets>=4.2 in /usr/local/lib/python3.12/dist-packages (from ipython>=6.0->watermark) (5.7.1)
Requirement already satisfied: prompt-toolkit!=3.0.0,!=3.0.1,<3.1.0,>=2.0.0 in /usr/local/lib/python3.12/dist-packages (from ipython>=6.0->watermark) (3.0.52)
Requirement already satisfied: pygments in /usr/local/lib/python3.12/dist-packages (from ipython>=6.0->watermark) (2.19.2)
Requirement already satisfied: backcall in /usr/local/lib/python3.12/dist-packages (from ipython>=6.0->watermark) (0.2.0)
Requirement already satisfied: matplotlib-inline in /usr/local/lib/python3.12/dist-packages (from ipython>=6.0->watermark) (0.2.1)
Requirement already satisfied: pexpect>4.3 in /usr/local/lib/python3.12/dist-packages (from ipython>=6.0->watermark) (4.9.0)
Requirement already satisfied: parso<0.9.0,>=0.8.4 in /usr/local/lib/python3.12/dist-packages (from jedi>=0.16->ipython>=6.0->watermark) (0.8.5)
Requirement already satisfied: ptyprocess>=0.5 in /usr/local/lib/python3.12/dist-packages (from pexpect>4.3->ipython>=6.0->watermark) (0.7.0)
Requirement already satisfied: wcwidth in /usr/local/lib/python3.12/dist-packages (from prompt-toolkit!=3.0.0,!=3.0.1,<3.1.0,>=2.0.0->ipython>=6.0->watermark) (0.2.14)
Downloading watermark-2.6.0-py3-none-any.whl (13 kB)
Downloading jedi-0.19.2-py2.py3-none-any.whl (1.6 MB)
   ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 1.6/1.6 MB 22.3 MB/s eta 0:00:00
Installing collected packages: jedi, watermark
Successfully installed jedi-0.19.2 watermark-2.6.0
In [2]:
!pip install torchinfo
Collecting torchinfo
  Downloading torchinfo-1.8.0-py3-none-any.whl.metadata (21 kB)
Downloading torchinfo-1.8.0-py3-none-any.whl (23 kB)
Installing collected packages: torchinfo
Successfully installed torchinfo-1.8.0
In [3]:
%load_ext watermark
# %reload_ext watermark
%watermark -a 'Chizoba Obasi' -v -p torch
Author: Chizoba Obasi

Python implementation: CPython
Python version       : 3.12.12
IPython version      : 7.34.0

torch: 2.9.0+cu126
MobileNetV3-Small Classifier on CIFAR-10
This notebook implements MobileNetV3-Small [1] and applies it to the CIFAR-10 dataset.
Network Architecture

MobileNet-V3: Bottleneck Block
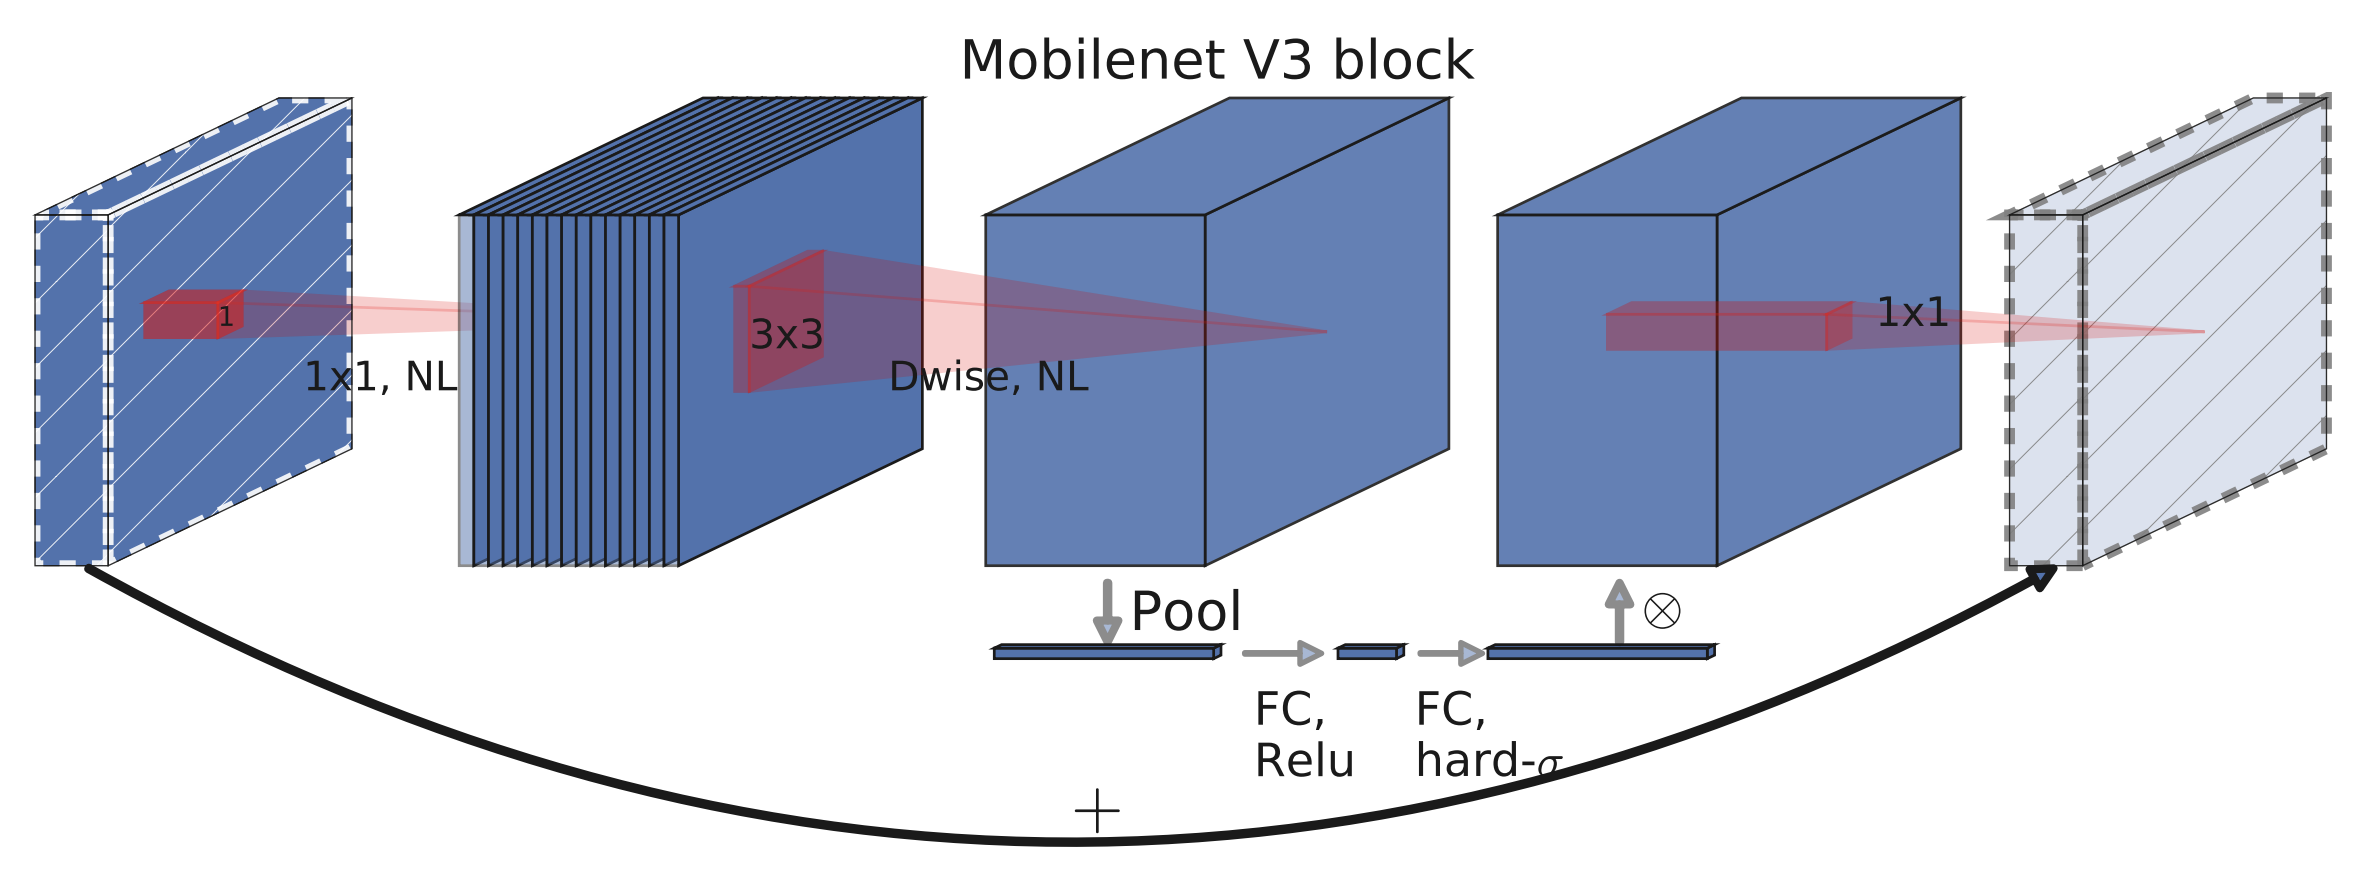
MobileNet-Vx: Backbone Block
| MobileNetV2 | MobileNetV3 |
|---|---|
 Source |
 Source |
REFERENCES:
- Howard, M., et al. "Searching for MobileNetV3." CVPR, 2018.
- Johnson, J. (2022, February 2). Lecture 11: CNN Architectures, Part 2 [PowerPoint Slides]. University of Michigan EECS 498/598: Deep Learning for Computer Vision. pp 44-53. https://web.eecs.umich.edu/~justincj/slides/eecs498/WI2022/598_WI2022_lecture11.pdf
In [4]:
import torch
import torchvision
import torch.nn as nn
import torch.nn.functional as F
import torch.optim as optim
from torch.utils.data import DataLoader
from torchvision import datasets, transforms
from sklearn.model_selection import train_test_split

from torchinfo import summary

import matplotlib.image as mpimg
import matplotlib.pyplot as plt
%matplotlib inline

import pandas as pd
import numpy as np
import math
import time
import os
import random

if torch.cuda.is_available():
    torch.backends.cudnn.deterministic = True
In [5]:
def set_all_seeds(seed):
    os.environ["PL_GLOBAL_SEED"] = str(seed)
    random.seed(seed)
    np.random.seed(seed)
    torch.manual_seed(seed)
    torch.cuda.manual_seed_all(seed)
In [6]:
# Check if GPU is available and set the device
if torch.cuda.is_available():
    num_gpus = torch.cuda.device_count()
    print("Num GPUs Available: ", num_gpus)
    for i in range(num_gpus):
        gpu_name = torch.cuda.get_device_name(i)
        print(f"GPU {i}: {gpu_name}")
else:
    print("No GPU available.")
Num GPUs Available:  1
GPU 0: Tesla T4
In [7]:
##########################
### SETTINGS
##########################

# Hyperparameters
RANDOM_SEED = 123
BATCH_SIZE = 128 #256
LEARNING_RATE = 0.001
NUM_EPOCHS = 50 #30
INPUT_SIZE = 32 # CIFAR-10 is 32x32
NUM_CLASSES = 10

# Set device
device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
print(device)
cuda
In [8]:
set_all_seeds(RANDOM_SEED)
1. Data Preparation & Loading
Notes:
- Since we adjust the model to handle the CIFAR images natively, we should remove the
Resize((xx, yy))from your transforms. It will make ythe training 10x faster and use significantly less memory.
In [9]:
# CIFAR-10 specific stats (MEAN_arr, STD_arr)
stats = ((0.4914, 0.4822, 0.4465), (0.2471, 0.2435, 0.2616)) #(0.2023, 0.1994, 0.2010))

train_transforms = transforms.Compose([
    transforms.RandomCrop(32, padding=4), # Standard CIFAR augmentation
    transforms.RandomHorizontalFlip(),
    transforms.ToTensor(),
    transforms.Normalize(*stats)
])

test_transforms = transforms.Compose([
    transforms.ToTensor(),
    transforms.Normalize(*stats)
])

# Load Datasets
train_dataset = datasets.CIFAR10(root='./data', train=True, download=True, transform=train_transforms)
test_dataset = datasets.CIFAR10(root='./data', train=False, download=True, transform=test_transforms)

# Split training set into training and validation sets
train_size = int(0.9 * len(train_dataset))
val_size = len(train_dataset) - train_size
train_subset, val_subset = torch.utils.data.random_split(train_dataset, [train_size, val_size])

# Create DataLoaders
train_loader = DataLoader(train_subset, batch_size=BATCH_SIZE, shuffle=True, num_workers=2, pin_memory=True)
val_loader = DataLoader(val_subset, batch_size=BATCH_SIZE, shuffle=False, num_workers=2, pin_memory=True)
test_loader = DataLoader(test_dataset, batch_size=BATCH_SIZE, shuffle=False, num_workers=2, pin_memory=True)

classes = ('plane', 'car', 'bird', 'cat', 'deer', 'dog', 'frog', 'horse', 'ship', 'truck')
100%|██████████| 170M/170M [00:03<00:00, 42.8MB/s]
In [10]:
# Checking the dataset
for images, labels in train_loader:
    print('Image batch dimensions:', images.shape)
    print('Image label dimensions:', labels.shape)
    print('Class labels of 10 examples:', labels[:10])
    break
Image batch dimensions: torch.Size([128, 3, 32, 32])
Image label dimensions: torch.Size([128])
Class labels of 10 examples: tensor([2, 7, 4, 7, 0, 1, 1, 6, 9, 2])
In [11]:
plt.figure(figsize=(8, 8))
plt.axis("off")
plt.title("Training Images")
plt.imshow(np.transpose(torchvision.utils.make_grid(images[:64],
                                         padding=2, normalize=True),
                        (1, 2, 0)))
Out[11]:
<matplotlib.image.AxesImage at 0x7885cdb71910>

2. Model Creation
Notes:
- For CIFAR-10, we modify the original architecture by setting the initial convolution stride to 1 instead of 2. This prevents the $32 \times 32$ image from shrinking too fast.
In [12]:
def _make_divisible(v, divisor, min_value=None):
    """ Ensure all layers have a channel count divisible by 8 """
    if min_value is None:
        min_value = divisor
    new_v = max(min_value, int(v + divisor / 2) // divisor * divisor)
    if new_v < 0.9 * v:
        new_v += divisor
    return new_v

class HSwish(nn.Module):
    """
    Hard-Swish activation: professional fallback implementation.
    """
    def __init__(self, inplace: bool = True):
        super(HSwish, self).__init__()
        self.inplace = inplace

    def forward(self, x: torch.Tensor) -> torch.Tensor:
        if hasattr(F, 'hardswish'):
            return F.hardswish(x, inplace=self.inplace)
        return x * F.relu6(x + 3, inplace=self.inplace) / 6

class SqueezeExcitation(nn.Module):
    """
    SE Block: Learns to weight channels based on their importance.
    """
    def __init__(self, in_channels, reduction=4):
        super(SqueezeExcitation, self).__init__()
        # Ensure channel counts are divisible by 8 for hardware efficiency
        squeeze_channels = _make_divisible(in_channels // reduction, 8)

        self.se = nn.Sequential(
            nn.AdaptiveAvgPool2d(1),
            nn.Conv2d(in_channels, squeeze_channels, kernel_size=1),
            nn.ReLU(inplace=True),
            nn.Conv2d(squeeze_channels, in_channels, kernel_size=1),
            nn.Hardsigmoid(inplace=True)
        )

    def forward(self, x):
        return x * self.se(x)

class Block(nn.Module):
    def __init__(self, kernel_size, in_channels, expand_size, out_channels, se, nl, stride):
        super().__init__()
        self.stride = stride
        self.use_se = se
        self.use_res_connect = self.stride == 1 and in_channels == out_channels

        activation = HSwish if nl == 'HS' else nn.ReLU

        # Expansion
        self.conv1 = nn.Conv2d(in_channels, expand_size, 1, 1, 0, bias=False)
        self.bn1 = nn.BatchNorm2d(expand_size)
        self.act1 = activation(inplace=True)

        # Depthwise
        self.conv2 = nn.Conv2d(expand_size, expand_size, kernel_size, stride, kernel_size//2, groups=expand_size, bias=False)
        self.bn2 = nn.BatchNorm2d(expand_size)
        self.act2 = activation(inplace=True)

        # SE Block
        self.se = SqueezeExcitation(expand_size) if se else nn.Identity()

        # Projection (Linear)
        self.conv3 = nn.Conv2d(expand_size, out_channels, 1, 1, 0, bias=False)
        self.bn3 = nn.BatchNorm2d(out_channels)

    def forward(self, x):
        out = self.act1(self.bn1(self.conv1(x)))
        out = self.act2(self.bn2(self.conv2(out)))
        out = self.se(out)
        out = self.bn3(self.conv3(out))

        if self.use_res_connect:
            return x + out
        return out

class MobileNetV3_Small(nn.Module):
    def __init__(self, num_classes=10):
        super().__init__()

        # kernel, exp, out, se, nl, stride
        self.config = [
            [3, 16,  16,  True,  'RE', 2],
            [3, 72,  24,  False, 'RE', 2],
            [3, 88,  24,  False, 'RE', 1],
            [5, 96,  40,  True,  'HS', 2],
            [5, 240, 40,  True,  'HS', 1],
            [5, 240, 40,  True,  'HS', 1],
            [5, 120, 48,  True,  'HS', 1],
            [5, 144, 48,  True,  'HS', 1],
            [5, 288, 96,  True,  'HS', 2],
            [5, 576, 96,  True,  'HS', 1],
            [5, 576, 96,  True,  'HS', 1],
        ]

        # First Layer
        self.conv1 = nn.Conv2d(3, 16, 3, 1, 1, bias=False) # Modified first layer: Stride 1 for CIFAR-10
        self.bn1 = nn.BatchNorm2d(16)
        self.act1 = HSwish(inplace=True)

        # Build Blocks
        layers = []
        in_channels = 16
        for k, exp, out, se, nl, s in self.config:
            layers.append(Block(k, in_channels, exp, out, se, nl, s))
            in_channels = out
        self.blocks = nn.Sequential(*layers)

        # Final Layers
        last_out = 576
        self.conv2 = nn.Conv2d(in_channels, last_out, 1, 1, 0, bias=False)
        self.bn2 = nn.BatchNorm2d(last_out)
        self.act2 = HSwish(inplace=True)

        self.avgpool = nn.AdaptiveAvgPool2d(1)
        self.fc = nn.Sequential(
            nn.Linear(last_out, 1024),
            HSwish(inplace=True),
            nn.Dropout(0.2),
            nn.Linear(1024, num_classes)
        )

    def forward(self, x):
        x = self.act1(self.bn1(self.conv1(x)))
        x = self.blocks(x)
        x = self.act2(self.bn2(self.conv2(x)))
        x = self.avgpool(x)
        x = x.view(x.size(0), -1)
        return self.fc(x)
In [13]:
model = MobileNetV3_Small().to(device)
In [14]:
# Model parameter details
summary(model,
        input_size=(BATCH_SIZE, 3, INPUT_SIZE, INPUT_SIZE),
        # verbose=1,
        col_names=["input_size", "output_size", "num_params", "kernel_size", "mult_adds"]
       )
Out[14]:
=============================================================================================================================================================================== Layer (type:depth-idx) Input Shape Output Shape Param # Kernel Shape Mult-Adds =============================================================================================================================================================================== MobileNetV3_Small [128, 3, 32, 32] [128, 10] -- -- -- ├─Conv2d: 1-1 [128, 3, 32, 32] [128, 16, 32, 32] 432 [3, 3] 56,623,104 ├─BatchNorm2d: 1-2 [128, 16, 32, 32] [128, 16, 32, 32] 32 -- 4,096 ├─HSwish: 1-3 [128, 16, 32, 32] [128, 16, 32, 32] -- -- -- ├─Sequential: 1-4 [128, 16, 32, 32] [128, 96, 2, 2] -- -- -- │ └─Block: 2-1 [128, 16, 32, 32] [128, 16, 16, 16] -- -- -- │ │ └─Conv2d: 3-1 [128, 16, 32, 32] [128, 16, 32, 32] 256 [1, 1] 33,554,432 │ │ └─BatchNorm2d: 3-2 [128, 16, 32, 32] [128, 16, 32, 32] 32 -- 4,096 │ │ └─ReLU: 3-3 [128, 16, 32, 32] [128, 16, 32, 32] -- -- -- │ │ └─Conv2d: 3-4 [128, 16, 32, 32] [128, 16, 16, 16] 144 [3, 3] 4,718,592 │ │ └─BatchNorm2d: 3-5 [128, 16, 16, 16] [128, 16, 16, 16] 32 -- 4,096 │ │ └─ReLU: 3-6 [128, 16, 16, 16] [128, 16, 16, 16] -- -- -- │ │ └─SqueezeExcitation: 3-7 [128, 16, 16, 16] [128, 16, 16, 16] 280 -- 35,840 │ │ └─Conv2d: 3-8 [128, 16, 16, 16] [128, 16, 16, 16] 256 [1, 1] 8,388,608 │ │ └─BatchNorm2d: 3-9 [128, 16, 16, 16] [128, 16, 16, 16] 32 -- 4,096 │ └─Block: 2-2 [128, 16, 16, 16] [128, 24, 8, 8] -- -- -- │ │ └─Conv2d: 3-10 [128, 16, 16, 16] [128, 72, 16, 16] 1,152 [1, 1] 37,748,736 │ │ └─BatchNorm2d: 3-11 [128, 72, 16, 16] [128, 72, 16, 16] 144 -- 18,432 │ │ └─ReLU: 3-12 [128, 72, 16, 16] [128, 72, 16, 16] -- -- -- │ │ └─Conv2d: 3-13 [128, 72, 16, 16] [128, 72, 8, 8] 648 [3, 3] 5,308,416 │ │ └─BatchNorm2d: 3-14 [128, 72, 8, 8] [128, 72, 8, 8] 144 -- 18,432 │ │ └─ReLU: 3-15 [128, 72, 8, 8] [128, 72, 8, 8] -- -- -- │ │ └─Identity: 3-16 [128, 72, 8, 8] [128, 72, 8, 8] -- -- -- │ │ └─Conv2d: 3-17 [128, 72, 8, 8] [128, 24, 8, 8] 1,728 [1, 1] 14,155,776 │ │ └─BatchNorm2d: 3-18 [128, 24, 8, 8] [128, 24, 8, 8] 48 -- 6,144 │ └─Block: 2-3 [128, 24, 8, 8] [128, 24, 8, 8] -- -- -- │ │ └─Conv2d: 3-19 [128, 24, 8, 8] [128, 88, 8, 8] 2,112 [1, 1] 17,301,504 │ │ └─BatchNorm2d: 3-20 [128, 88, 8, 8] [128, 88, 8, 8] 176 -- 22,528 │ │ └─ReLU: 3-21 [128, 88, 8, 8] [128, 88, 8, 8] -- -- -- │ │ └─Conv2d: 3-22 [128, 88, 8, 8] [128, 88, 8, 8] 792 [3, 3] 6,488,064 │ │ └─BatchNorm2d: 3-23 [128, 88, 8, 8] [128, 88, 8, 8] 176 -- 22,528 │ │ └─ReLU: 3-24 [128, 88, 8, 8] [128, 88, 8, 8] -- -- -- │ │ └─Identity: 3-25 [128, 88, 8, 8] [128, 88, 8, 8] -- -- -- │ │ └─Conv2d: 3-26 [128, 88, 8, 8] [128, 24, 8, 8] 2,112 [1, 1] 17,301,504 │ │ └─BatchNorm2d: 3-27 [128, 24, 8, 8] [128, 24, 8, 8] 48 -- 6,144 │ └─Block: 2-4 [128, 24, 8, 8] [128, 40, 4, 4] -- -- -- │ │ └─Conv2d: 3-28 [128, 24, 8, 8] [128, 96, 8, 8] 2,304 [1, 1] 18,874,368 │ │ └─BatchNorm2d: 3-29 [128, 96, 8, 8] [128, 96, 8, 8] 192 -- 24,576 │ │ └─HSwish: 3-30 [128, 96, 8, 8] [128, 96, 8, 8] -- -- -- │ │ └─Conv2d: 3-31 [128, 96, 8, 8] [128, 96, 4, 4] 2,400 [5, 5] 4,915,200 │ │ └─BatchNorm2d: 3-32 [128, 96, 4, 4] [128, 96, 4, 4] 192 -- 24,576 │ │ └─HSwish: 3-33 [128, 96, 4, 4] [128, 96, 4, 4] -- -- -- │ │ └─SqueezeExcitation: 3-34 [128, 96, 4, 4] [128, 96, 4, 4] 4,728 -- 605,184 │ │ └─Conv2d: 3-35 [128, 96, 4, 4] [128, 40, 4, 4] 3,840 [1, 1] 7,864,320 │ │ └─BatchNorm2d: 3-36 [128, 40, 4, 4] [128, 40, 4, 4] 80 -- 10,240 │ └─Block: 2-5 [128, 40, 4, 4] [128, 40, 4, 4] -- -- -- │ │ └─Conv2d: 3-37 [128, 40, 4, 4] [128, 240, 4, 4] 9,600 [1, 1] 19,660,800 │ │ └─BatchNorm2d: 3-38 [128, 240, 4, 4] [128, 240, 4, 4] 480 -- 61,440 │ │ └─HSwish: 3-39 [128, 240, 4, 4] [128, 240, 4, 4] -- -- -- │ │ └─Conv2d: 3-40 [128, 240, 4, 4] [128, 240, 4, 4] 6,000 [5, 5] 12,288,000 │ │ └─BatchNorm2d: 3-41 [128, 240, 4, 4] [128, 240, 4, 4] 480 -- 61,440 │ │ └─HSwish: 3-42 [128, 240, 4, 4] [128, 240, 4, 4] -- -- -- │ │ └─SqueezeExcitation: 3-43 [128, 240, 4, 4] [128, 240, 4, 4] 31,024 -- 3,971,072 │ │ └─Conv2d: 3-44 [128, 240, 4, 4] [128, 40, 4, 4] 9,600 [1, 1] 19,660,800 │ │ └─BatchNorm2d: 3-45 [128, 40, 4, 4] [128, 40, 4, 4] 80 -- 10,240 │ └─Block: 2-6 [128, 40, 4, 4] [128, 40, 4, 4] -- -- -- │ │ └─Conv2d: 3-46 [128, 40, 4, 4] [128, 240, 4, 4] 9,600 [1, 1] 19,660,800 │ │ └─BatchNorm2d: 3-47 [128, 240, 4, 4] [128, 240, 4, 4] 480 -- 61,440 │ │ └─HSwish: 3-48 [128, 240, 4, 4] [128, 240, 4, 4] -- -- -- │ │ └─Conv2d: 3-49 [128, 240, 4, 4] [128, 240, 4, 4] 6,000 [5, 5] 12,288,000 │ │ └─BatchNorm2d: 3-50 [128, 240, 4, 4] [128, 240, 4, 4] 480 -- 61,440 │ │ └─HSwish: 3-51 [128, 240, 4, 4] [128, 240, 4, 4] -- -- -- │ │ └─SqueezeExcitation: 3-52 [128, 240, 4, 4] [128, 240, 4, 4] 31,024 -- 3,971,072 │ │ └─Conv2d: 3-53 [128, 240, 4, 4] [128, 40, 4, 4] 9,600 [1, 1] 19,660,800 │ │ └─BatchNorm2d: 3-54 [128, 40, 4, 4] [128, 40, 4, 4] 80 -- 10,240 │ └─Block: 2-7 [128, 40, 4, 4] [128, 48, 4, 4] -- -- -- │ │ └─Conv2d: 3-55 [128, 40, 4, 4] [128, 120, 4, 4] 4,800 [1, 1] 9,830,400 │ │ └─BatchNorm2d: 3-56 [128, 120, 4, 4] [128, 120, 4, 4] 240 -- 30,720 │ │ └─HSwish: 3-57 [128, 120, 4, 4] [128, 120, 4, 4] -- -- -- │ │ └─Conv2d: 3-58 [128, 120, 4, 4] [128, 120, 4, 4] 3,000 [5, 5] 6,144,000 │ │ └─BatchNorm2d: 3-59 [128, 120, 4, 4] [128, 120, 4, 4] 240 -- 30,720 │ │ └─HSwish: 3-60 [128, 120, 4, 4] [128, 120, 4, 4] -- -- -- │ │ └─SqueezeExcitation: 3-61 [128, 120, 4, 4] [128, 120, 4, 4] 7,832 -- 1,002,496 │ │ └─Conv2d: 3-62 [128, 120, 4, 4] [128, 48, 4, 4] 5,760 [1, 1] 11,796,480 │ │ └─BatchNorm2d: 3-63 [128, 48, 4, 4] [128, 48, 4, 4] 96 -- 12,288 │ └─Block: 2-8 [128, 48, 4, 4] [128, 48, 4, 4] -- -- -- │ │ └─Conv2d: 3-64 [128, 48, 4, 4] [128, 144, 4, 4] 6,912 [1, 1] 14,155,776 │ │ └─BatchNorm2d: 3-65 [128, 144, 4, 4] [128, 144, 4, 4] 288 -- 36,864 │ │ └─HSwish: 3-66 [128, 144, 4, 4] [128, 144, 4, 4] -- -- -- │ │ └─Conv2d: 3-67 [128, 144, 4, 4] [128, 144, 4, 4] 3,600 [5, 5] 7,372,800 │ │ └─BatchNorm2d: 3-68 [128, 144, 4, 4] [128, 144, 4, 4] 288 -- 36,864 │ │ └─HSwish: 3-69 [128, 144, 4, 4] [128, 144, 4, 4] -- -- -- │ │ └─SqueezeExcitation: 3-70 [128, 144, 4, 4] [128, 144, 4, 4] 11,704 -- 1,498,112 │ │ └─Conv2d: 3-71 [128, 144, 4, 4] [128, 48, 4, 4] 6,912 [1, 1] 14,155,776 │ │ └─BatchNorm2d: 3-72 [128, 48, 4, 4] [128, 48, 4, 4] 96 -- 12,288 │ └─Block: 2-9 [128, 48, 4, 4] [128, 96, 2, 2] -- -- -- │ │ └─Conv2d: 3-73 [128, 48, 4, 4] [128, 288, 4, 4] 13,824 [1, 1] 28,311,552 │ │ └─BatchNorm2d: 3-74 [128, 288, 4, 4] [128, 288, 4, 4] 576 -- 73,728 │ │ └─HSwish: 3-75 [128, 288, 4, 4] [128, 288, 4, 4] -- -- -- │ │ └─Conv2d: 3-76 [128, 288, 4, 4] [128, 288, 2, 2] 7,200 [5, 5] 3,686,400 │ │ └─BatchNorm2d: 3-77 [128, 288, 2, 2] [128, 288, 2, 2] 576 -- 73,728 │ │ └─HSwish: 3-78 [128, 288, 2, 2] [128, 288, 2, 2] -- -- -- │ │ └─SqueezeExcitation: 3-79 [128, 288, 2, 2] [128, 288, 2, 2] 41,832 -- 5,354,496 │ │ └─Conv2d: 3-80 [128, 288, 2, 2] [128, 96, 2, 2] 27,648 [1, 1] 14,155,776 │ │ └─BatchNorm2d: 3-81 [128, 96, 2, 2] [128, 96, 2, 2] 192 -- 24,576 │ └─Block: 2-10 [128, 96, 2, 2] [128, 96, 2, 2] -- -- -- │ │ └─Conv2d: 3-82 [128, 96, 2, 2] [128, 576, 2, 2] 55,296 [1, 1] 28,311,552 │ │ └─BatchNorm2d: 3-83 [128, 576, 2, 2] [128, 576, 2, 2] 1,152 -- 147,456 │ │ └─HSwish: 3-84 [128, 576, 2, 2] [128, 576, 2, 2] -- -- -- │ │ └─Conv2d: 3-85 [128, 576, 2, 2] [128, 576, 2, 2] 14,400 [5, 5] 7,372,800 │ │ └─BatchNorm2d: 3-86 [128, 576, 2, 2] [128, 576, 2, 2] 1,152 -- 147,456 │ │ └─HSwish: 3-87 [128, 576, 2, 2] [128, 576, 2, 2] -- -- -- │ │ └─SqueezeExcitation: 3-88 [128, 576, 2, 2] [128, 576, 2, 2] 166,608 -- 21,325,824 │ │ └─Conv2d: 3-89 [128, 576, 2, 2] [128, 96, 2, 2] 55,296 [1, 1] 28,311,552 │ │ └─BatchNorm2d: 3-90 [128, 96, 2, 2] [128, 96, 2, 2] 192 -- 24,576 │ └─Block: 2-11 [128, 96, 2, 2] [128, 96, 2, 2] -- -- -- │ │ └─Conv2d: 3-91 [128, 96, 2, 2] [128, 576, 2, 2] 55,296 [1, 1] 28,311,552 │ │ └─BatchNorm2d: 3-92 [128, 576, 2, 2] [128, 576, 2, 2] 1,152 -- 147,456 │ │ └─HSwish: 3-93 [128, 576, 2, 2] [128, 576, 2, 2] -- -- -- │ │ └─Conv2d: 3-94 [128, 576, 2, 2] [128, 576, 2, 2] 14,400 [5, 5] 7,372,800 │ │ └─BatchNorm2d: 3-95 [128, 576, 2, 2] [128, 576, 2, 2] 1,152 -- 147,456 │ │ └─HSwish: 3-96 [128, 576, 2, 2] [128, 576, 2, 2] -- -- -- │ │ └─SqueezeExcitation: 3-97 [128, 576, 2, 2] [128, 576, 2, 2] 166,608 -- 21,325,824 │ │ └─Conv2d: 3-98 [128, 576, 2, 2] [128, 96, 2, 2] 55,296 [1, 1] 28,311,552 │ │ └─BatchNorm2d: 3-99 [128, 96, 2, 2] [128, 96, 2, 2] 192 -- 24,576 ├─Conv2d: 1-5 [128, 96, 2, 2] [128, 576, 2, 2] 55,296 [1, 1] 28,311,552 ├─BatchNorm2d: 1-6 [128, 576, 2, 2] [128, 576, 2, 2] 1,152 -- 147,456 ├─HSwish: 1-7 [128, 576, 2, 2] [128, 576, 2, 2] -- -- -- ├─AdaptiveAvgPool2d: 1-8 [128, 576, 2, 2] [128, 576, 1, 1] -- -- -- ├─Sequential: 1-9 [128, 576] [128, 10] -- -- -- │ └─Linear: 2-12 [128, 576] [128, 1024] 590,848 -- 75,628,544 │ └─HSwish: 2-13 [128, 1024] [128, 1024] -- -- -- │ └─Dropout: 2-14 [128, 1024] [128, 1024] -- -- -- │ └─Linear: 2-15 [128, 1024] [128, 10] 10,250 -- 1,312,000 =============================================================================================================================================================================== Total params: 1,528,394 Trainable params: 1,528,394 Non-trainable params: 0 Total mult-adds (Units.MEGABYTES): 739.96 =============================================================================================================================================================================== Input size (MB): 1.57 Forward/backward pass size (MB): 273.76 Params size (MB): 6.11 Estimated Total Size (MB): 281.45 ===============================================================================================================================================================================
In [15]:
criterion = nn.CrossEntropyLoss()
optimizer = optim.Adam(model.parameters(), lr=LEARNING_RATE, weight_decay=5e-4)
# optimizer = optim.SGD(model.parameters(), lr=LEARNING_RATE, momentum=0.9, weight_decay=5e-4) # Use weight decay (L2) to combat overfitting
# scheduler = optim.lr_scheduler.ReduceLROnPlateau(optimizer, mode='min', factor=0.1, patience=5)

def calculate_accuracy(loader):
    model.eval()
    correct = 0
    total = 0
    with torch.no_grad():
        for inputs, labels in loader:
            inputs, labels = inputs.to(device), labels.to(device)
            outputs = model(inputs)
            _, predicted = torch.max(outputs.data, 1)
            total += labels.size(0)
            correct += (predicted == labels).sum().item()
    return 100 * correct / total

# Training Loop
start_time = time.time()
history = {'train_loss': [], 'val_loss': [], 'train_acc': [], 'val_acc': [], 'lrs': []}

print(f"Starting training on {device}...")

for epoch in range(NUM_EPOCHS):
    model.train()
    running_loss = 0.0

    for i, (inputs, labels) in enumerate(train_loader):
        inputs, labels = inputs.to(device), labels.to(device)

        optimizer.zero_grad()
        outputs = model(inputs)
        loss = criterion(outputs, labels)
        loss.backward()
        optimizer.step()

        running_loss += loss.item() * inputs.size(0)

    train_loss = running_loss / len(train_subset)
    train_acc = calculate_accuracy(train_loader)

    # Calculate validation loss and accuracy
    model.eval()
    val_loss = 0.0
    with torch.no_grad():
        for inputs, labels in val_loader:
            inputs, labels = inputs.to(device), labels.to(device)
            outputs = model(inputs)
            loss = criterion(outputs, labels)
            val_loss += loss.item() * inputs.size(0)

    val_loss /= len(val_subset)
    val_acc = calculate_accuracy(val_loader)

    # scheduler.step(val_loss)
    # current_lr = optimizer.param_groups[0]['lr']

    # Log metrics
    history['train_loss'].append(train_loss)
    history['val_loss'].append(val_loss)
    history['train_acc'].append(train_acc)
    history['val_acc'].append(val_acc)
    # history['lrs'].append(current_lr)

    print(f'Epoch {epoch + 1}/{NUM_EPOCHS} | '
          f'Train Loss: {train_loss:.5f}, '
          f'Train Acc.: {train_acc:.2f}% | '
          f'Val Loss: {val_loss:.5f}, '
          f'Val Acc.: {val_acc:.2f}% | '
          # f'LR: {current_lr:.8f}')
         )

print('\nTotal Training Time: %.2f min' % ((time.time() - start_time)/60))

# --- Final Evaluation ---
test_accuracy = calculate_accuracy(test_loader)
print(f'\nTest Accuracy: {test_accuracy:.2f}%')
Starting training on cuda...
Epoch 1/50 | Train Loss: 1.73065, Train Acc.: 45.28% | Val Loss: 1.53673, Val Acc.: 43.54% |
Epoch 2/50 | Train Loss: 1.39979, Train Acc.: 50.15% | Val Loss: 1.43510, Val Acc.: 48.80% |
Epoch 3/50 | Train Loss: 1.24515, Train Acc.: 57.80% | Val Loss: 1.21370, Val Acc.: 56.30% |
Epoch 4/50 | Train Loss: 1.13354, Train Acc.: 59.95% | Val Loss: 1.16238, Val Acc.: 58.76% |
Epoch 5/50 | Train Loss: 1.04596, Train Acc.: 64.00% | Val Loss: 1.07061, Val Acc.: 62.18% |
Epoch 6/50 | Train Loss: 0.97225, Train Acc.: 67.27% | Val Loss: 0.97296, Val Acc.: 64.78% |
Epoch 7/50 | Train Loss: 0.92086, Train Acc.: 68.61% | Val Loss: 0.96091, Val Acc.: 66.48% |
Epoch 8/50 | Train Loss: 0.87471, Train Acc.: 71.55% | Val Loss: 0.87404, Val Acc.: 68.30% |
Epoch 9/50 | Train Loss: 0.83071, Train Acc.: 71.61% | Val Loss: 0.86434, Val Acc.: 69.26% |
Epoch 10/50 | Train Loss: 0.80603, Train Acc.: 73.38% | Val Loss: 0.83139, Val Acc.: 70.28% |
Epoch 11/50 | Train Loss: 0.78059, Train Acc.: 74.64% | Val Loss: 0.79481, Val Acc.: 71.58% |
Epoch 12/50 | Train Loss: 0.75895, Train Acc.: 73.26% | Val Loss: 0.84107, Val Acc.: 71.46% |
Epoch 13/50 | Train Loss: 0.73304, Train Acc.: 74.71% | Val Loss: 0.77969, Val Acc.: 72.50% |
Epoch 14/50 | Train Loss: 0.71511, Train Acc.: 75.92% | Val Loss: 0.77488, Val Acc.: 72.82% |
Epoch 15/50 | Train Loss: 0.70061, Train Acc.: 76.41% | Val Loss: 0.75040, Val Acc.: 73.60% |
Epoch 16/50 | Train Loss: 0.68538, Train Acc.: 76.73% | Val Loss: 0.74324, Val Acc.: 74.46% |
Epoch 17/50 | Train Loss: 0.67344, Train Acc.: 77.93% | Val Loss: 0.70885, Val Acc.: 75.78% |
Epoch 18/50 | Train Loss: 0.66285, Train Acc.: 78.04% | Val Loss: 0.70071, Val Acc.: 75.68% |
Epoch 19/50 | Train Loss: 0.65244, Train Acc.: 78.90% | Val Loss: 0.68678, Val Acc.: 76.26% |
Epoch 20/50 | Train Loss: 0.63551, Train Acc.: 78.37% | Val Loss: 0.71000, Val Acc.: 74.42% |
Epoch 21/50 | Train Loss: 0.63549, Train Acc.: 78.77% | Val Loss: 0.71004, Val Acc.: 75.84% |
Epoch 22/50 | Train Loss: 0.62002, Train Acc.: 78.77% | Val Loss: 0.68675, Val Acc.: 75.98% |
Epoch 23/50 | Train Loss: 0.60936, Train Acc.: 80.38% | Val Loss: 0.64527, Val Acc.: 77.26% |
Epoch 24/50 | Train Loss: 0.59948, Train Acc.: 79.13% | Val Loss: 0.66488, Val Acc.: 76.54% |
Epoch 25/50 | Train Loss: 0.59560, Train Acc.: 79.98% | Val Loss: 0.65488, Val Acc.: 77.54% |
Epoch 26/50 | Train Loss: 0.57906, Train Acc.: 79.24% | Val Loss: 0.67419, Val Acc.: 77.48% |
Epoch 27/50 | Train Loss: 0.58304, Train Acc.: 81.20% | Val Loss: 0.61139, Val Acc.: 77.36% |
Epoch 28/50 | Train Loss: 0.57411, Train Acc.: 81.01% | Val Loss: 0.64602, Val Acc.: 77.94% |
Epoch 29/50 | Train Loss: 0.55920, Train Acc.: 81.13% | Val Loss: 0.63081, Val Acc.: 78.76% |
Epoch 30/50 | Train Loss: 0.55383, Train Acc.: 81.26% | Val Loss: 0.63215, Val Acc.: 77.86% |
Epoch 31/50 | Train Loss: 0.56046, Train Acc.: 82.18% | Val Loss: 0.59775, Val Acc.: 78.76% |
Epoch 32/50 | Train Loss: 0.55286, Train Acc.: 82.44% | Val Loss: 0.59665, Val Acc.: 79.94% |
Epoch 33/50 | Train Loss: 0.54350, Train Acc.: 82.91% | Val Loss: 0.58875, Val Acc.: 80.30% |
Epoch 34/50 | Train Loss: 0.53208, Train Acc.: 81.92% | Val Loss: 0.60535, Val Acc.: 78.82% |
Epoch 35/50 | Train Loss: 0.53693, Train Acc.: 81.44% | Val Loss: 0.64663, Val Acc.: 78.34% |
Epoch 36/50 | Train Loss: 0.52663, Train Acc.: 82.02% | Val Loss: 0.60403, Val Acc.: 77.90% |
Epoch 37/50 | Train Loss: 0.52616, Train Acc.: 81.53% | Val Loss: 0.63171, Val Acc.: 78.88% |
Epoch 38/50 | Train Loss: 0.52042, Train Acc.: 82.71% | Val Loss: 0.59814, Val Acc.: 79.22% |
Epoch 39/50 | Train Loss: 0.51995, Train Acc.: 83.54% | Val Loss: 0.55317, Val Acc.: 80.68% |
Epoch 40/50 | Train Loss: 0.51154, Train Acc.: 83.40% | Val Loss: 0.57716, Val Acc.: 79.90% |
Epoch 41/50 | Train Loss: 0.51099, Train Acc.: 82.82% | Val Loss: 0.60852, Val Acc.: 80.02% |
Epoch 42/50 | Train Loss: 0.50615, Train Acc.: 82.62% | Val Loss: 0.60404, Val Acc.: 79.42% |
Epoch 43/50 | Train Loss: 0.50277, Train Acc.: 83.50% | Val Loss: 0.57630, Val Acc.: 80.18% |
Epoch 44/50 | Train Loss: 0.49798, Train Acc.: 84.09% | Val Loss: 0.54885, Val Acc.: 80.76% |
Epoch 45/50 | Train Loss: 0.49817, Train Acc.: 83.56% | Val Loss: 0.56118, Val Acc.: 80.38% |
Epoch 46/50 | Train Loss: 0.49171, Train Acc.: 82.90% | Val Loss: 0.57896, Val Acc.: 80.06% |
Epoch 47/50 | Train Loss: 0.49581, Train Acc.: 83.76% | Val Loss: 0.54906, Val Acc.: 80.60% |
Epoch 48/50 | Train Loss: 0.48942, Train Acc.: 83.44% | Val Loss: 0.57848, Val Acc.: 80.18% |
Epoch 49/50 | Train Loss: 0.48989, Train Acc.: 83.17% | Val Loss: 0.58209, Val Acc.: 79.76% |
Epoch 50/50 | Train Loss: 0.48434, Train Acc.: 83.76% | Val Loss: 0.57219, Val Acc.: 80.20% |

Total Training Time: 37.85 min

Test Accuracy: 82.02%
In [16]:
def plot_history(history):
    """
    Plots the training and validation loss, accuracy, and learning rate
    from a PyTorch history dictionary.

    Args:
        history (dict): Dictionary containing training metrics.
                        Expected keys: 'train_loss', 'val_loss', 'train_acc', 'val_acc', 'lrs'.
    """
    epochs = range(len(history['train_loss']))

    plt.figure(figsize=(18, 5))

    # Plot 1: Loss
    plt.subplot(1, 3, 1)
    plt.plot(epochs, history['train_loss'], label='Training Loss')
    plt.plot(epochs, history['val_loss'], label='Validation Loss')
    plt.title('Loss')
    plt.xlabel('Epochs')
    plt.ylabel('Loss')
    plt.legend()
    # plt.grid(True)

    # Plot 2: Accuracy
    plt.subplot(1, 3, 2)
    plt.plot(epochs, history['train_acc'], label='Training Accuracy')
    plt.plot(epochs, history['val_acc'], label='Validation Accuracy')
    plt.title('Accuracy')
    plt.xlabel('Epochs')
    plt.ylabel('Accuracy')
    plt.legend()
    # plt.grid(True)

    plt.tight_layout()
    plt.show()
    # plt.savefig()
In [17]:
plot_history(history)

In [18]:
class_dict = {0: 'plane',
              1: 'car',
              2: 'bird',
              3: 'cat',
              4: 'deer',
              5: 'dog',
              6: 'frog',
              7: 'horse',
              8: 'ship',
              9: 'truck'}
In [19]:
from sklearn.metrics import confusion_matrix
import seaborn as sns

def _compute_confusion_matrix(model, data_loader, device):
    """
    Computes a confusion matrix for the given model and data.
    Uses scikit-learn for robustness and speed.
    """
    model.eval()
    all_targets = []
    all_predictions = []

    with torch.no_grad():
        for features, targets in data_loader:
            features = features.to(device)

            logits = model(features)
            _, predicted_labels = torch.max(logits, 1)

            # Move to CPU and convert to list/numpy immediately
            all_targets.extend(targets.view(-1).cpu().numpy())
            all_predictions.extend(predicted_labels.view(-1).cpu().numpy())

    return confusion_matrix(all_targets, all_predictions)

def _plot_confusion_matrix(mat, class_names):
    """
    Visualizes the confusion matrix using Seaborn for professional reporting.
    """
    plt.figure(figsize=(10, 8))
    sns.heatmap(mat, annot=True, fmt='d', cmap='Blues',
                xticklabels=class_names, yticklabels=class_names)
    plt.xlabel('Predicted Label')
    plt.ylabel('True Label')
    plt.title('Confusion Matrix: MobileNetV2 on CIFAR-10')
    plt.show()
In [20]:
_mat = _compute_confusion_matrix(model=model, data_loader=test_loader, device=device)
_plot_confusion_matrix(_mat, class_names=class_dict.values())

In [21]:
%watermark -iv
matplotlib : 3.10.0
numpy      : 2.0.2
pandas     : 2.2.2
seaborn    : 0.13.2
sklearn    : 1.6.1
torch      : 2.9.0+cu126
torchinfo  : 1.8.0
torchvision: 0.24.0+cu126
In [ ]: